

What Are the Main Parts of Unsupervised Learning?
- Starter
- Article
- Ages 10+
- 4 min read

Unsupervised learning is a type of machine learning in which a model learns based on patterns in unlabeled data. Nobody hands the program the right answers. A model can look for groups and relationships. IBM's overview names three main tasks: clustering, association and dimensionality reduction.
Contents
- Mixed data
- A program
- Groups it found
What you will learn
- Explain what unlabeled data is and how unsupervised learning uses it.
- Name the three tasks IBM's overview lists for unsupervised learning.
- Describe one everyday use for each task.
Before you start
Read the first article on artificial intelligence, so that you know what machine learning is.
What does unsupervised learning work with?
Unsupervised learning works with unlabeled data, which means examples that come with no answer attached. Think of a label as a name tag. A box of photos with a name tag on each one is labeled. The same box without tags is unlabeled.
In unsupervised machine learning, a program looks for patterns in unlabeled data. Supervised learning is different, because supervised learning algorithms use labeled data.
- Labeled (with tags)
- Unlabeled (no tags)
The program can find patterns or trends that people are not explicitly looking for. Suppose it looks through online sales data. It might identify different types of clients making purchases.
What is clustering?
Clustering is a data mining technique that groups unlabeled data based on its similarities or differences. Imagine sorting a pile of mixed buttons. You put round ones together and square ones together, and nobody told you the groups in advance.
One example from NIST is learning a function to cluster or group data points. IBM's overview gives Google News as an example of using unsupervised learning to group articles on the same story from various online news outlets.
- Group of circles
- Group of squares
- Group of triangles
What is an association rule?
IBM describes association-rule learning as a rule-based method for finding relationships between variables in a dataset. In a shop, a variable can be a product, and the method can find products that tend to go together; an association rule expresses one such relationship.
These methods are frequently used for market basket analysis, helping companies better understand relationships between different products.
- First item
- Second item
- Third item
What is dimensionality reduction?
Dimensionality reduction is used when a dataset has too many features, or dimensions. A simple illustration is selecting fewer features; other techniques, such as PCA, transform the data into a new representation.
It reduces the number of data inputs to a manageable size while preserving the integrity of the dataset as much as possible. Picture a long form with many boxes where only the most useful boxes are kept.
- Many details
- A funnel that reduces
- Fewer details
Real-world example
Try this with an adult. Use sheets of paper with different colours or drawings and arrange them into groups without naming the groups in advance. This illustrates finding groups by hand. Ask a friend to sort the same sheets, then compare the criteria each of you chose.
Common misunderstandings
Unsupervised learning needs nobody at all. IBM lists a challenge: human intervention to validate output variables.
The groups always come with a clear explanation. Another challenge IBM lists is a lack of transparency into the basis on which data was clustered.
Clustering is the whole of unsupervised learning. IBM lists clustering alongside association and dimensionality reduction among the three main tasks in its overview.
Frequently asked questions
What is the difference between supervised and unsupervised learning?
Supervised learning algorithms use labeled data. Unsupervised learning algorithms work with unlabeled data.
What is an example of unsupervised learning?
An unsupervised program could look through online sales data and identify different types of clients making purchases. IBM's overview also gives Google News as an example of grouping articles about the same story.
Is clustering the same as classification?
No. Clustering finds groups in unlabeled data. Supervised learning, explained in a separate article, uses labeled data.
Summary
- Unsupervised learning looks for patterns in unlabeled data.
- IBM's overview names three main tasks: clustering, association and dimensionality reduction.
- Its challenges include needing people to validate the output and a lack of transparency about how data was clustered.
Terms in this article
English and Vietnamese terms, with the meanings used here. Hover, tap or Tab to a term with a dotted underline for an explanation as you read.
- Unsupervised learningHọc không giám sát
- Machine learning that finds patterns and relationships in data without supplied answers.
- LabelNhãn
- An answer attached to an example; unsupervised-learning data does not come with these answers.
- Unlabeled dataDữ liệu không có nhãn
- Examples without supplied answers or category labels.
- ClusteringPhân cụm
- Grouping unlabelled data according to similarities or differences.
- Association ruleLuật kết hợp
- A relationship between variables found in data; association-rule mining is the method used to find such relationships.
- Dimensionality reductionGiảm chiều dữ liệu
- Reducing a dataset's dimensions, often by transforming it into a more compact representation while preserving as much information as possible.
- FeatureĐặc trưng
- An input or measured attribute recorded for an example. A dataset's features define its dimensions.
- Market basket analysisPhân tích giỏ hàng
- Analysing relationships between products in shopping data.
This article is not marked as viewed
Spotted something wrong or unsafe?
Tell the administrator by email. The message already has the article title and address.
More in this topic
 Starter
What Is Artificial Intelligence?
What artificial intelligence (AI) is, how it differs from human intelligence and how computers learn from data. A first article for complete beginners.
4 min read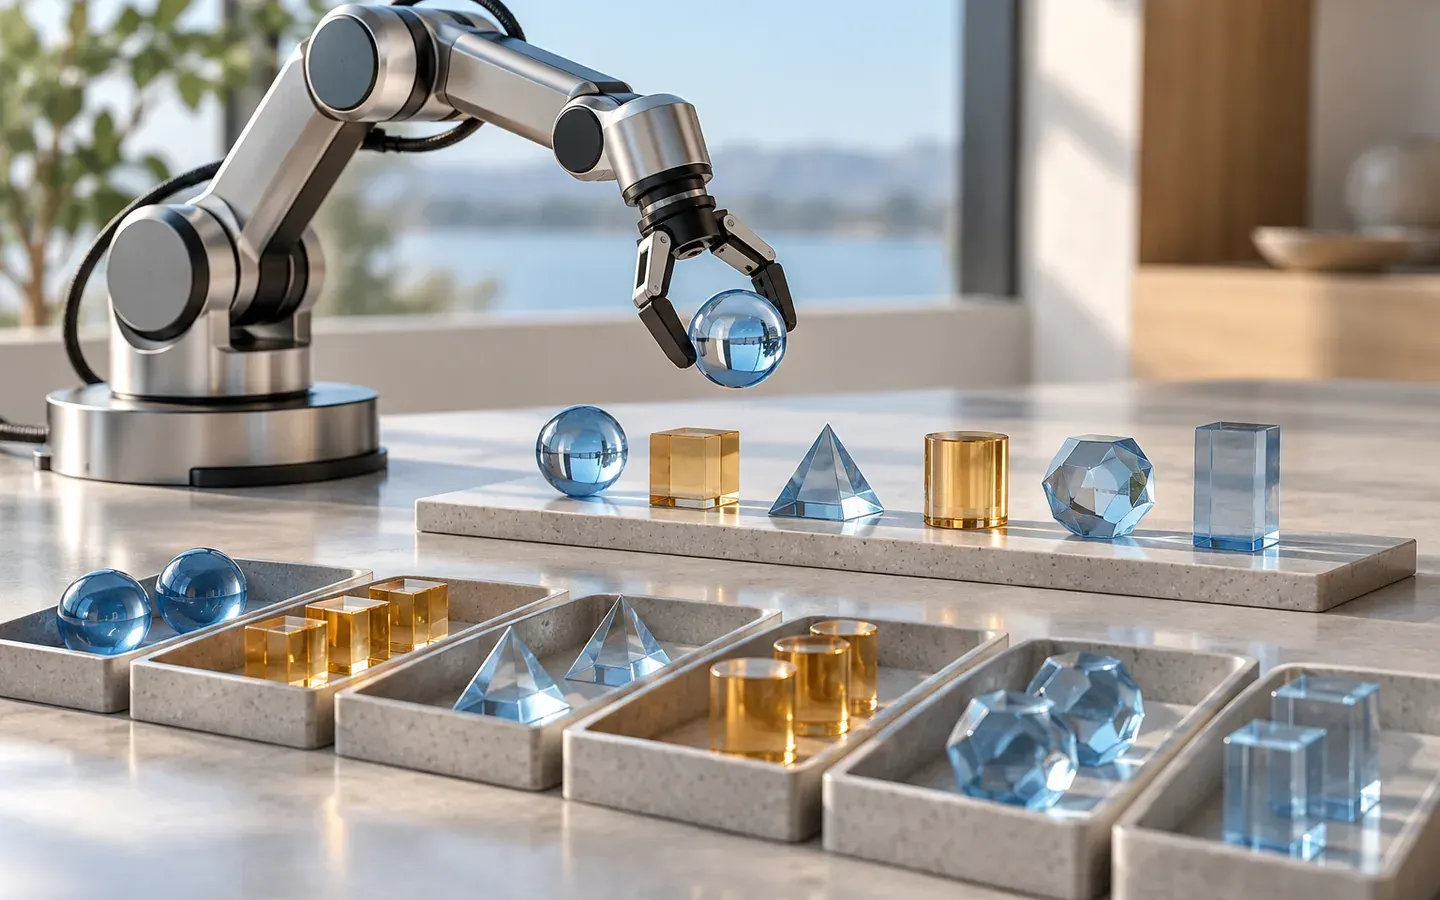 Starter
How Do Machines Learn?
How machines learn from examples: data, training, models and how they improve step by step. An opening article for beginners, to read with an adult.
4 min read Starter
Where Do We Encounter Supervised Learning?
What supervised learning is and where we meet it in daily life, from spam filters to image recognition. A starter article.
4 min read Starter
Why Does Reinforcement Learning Matter?
Reinforcement learning lets a machine learn by trial and error from rewards. See why this way of learning matters, explained for beginners.
4 min read


Sources
These sources are written for older readers. If they feel hard, read them with an adult.
- Machine learning, explained(opens in a new tab)
MIT Sloan School of ManagementTier A: government, standards or research bodiesRead on October 28, 2026
- unsupervised learning (NIST CSRC glossary)(opens in a new tab)
NISTTier A: government, standards or research bodiesRead on October 28, 2026
- What is unsupervised learning?(opens in a new tab)
IBMTier B: vendor documentationRead on October 28, 2026